What occurs when a frontier mannequin’s talents get packed into cheaper, quicker variations? That’s what OpenAI did with GPT-6 Sol and GPT-6 Luna, two new fashions constructed with strategies much like GPT-6 Astra. OpenAI is slicing API costs for each fashions by 50% in contrast with their GPT-5.6 variations, and says they carry Astra’s positive aspects in skilled work, factuality, coding, and laptop use to extra inexpensive tiers. On this article, we take a look at what’s new, break down the revealed benchmarks, run 4 hands-on exams, and flag the small print price studying twice.
GPT-6 Sol and Luna Options
These releases aren’t about topping the leaderboard; OpenAI says GPT-6 Astra stays its finest mannequin throughout the board. They’re about making that stage of intelligence cheaper to run every single day. All figures beneath come from OpenAI’s announcement and haven’t been independently verified.
Video Supply: OpenAI
Two fashions, two worth factors
GPT-6 Sol is the mid-tier mannequin, meant for demanding work at a decrease price than Astra, with larger utilization limits for extra iteration. Luna is the price range tier, constructed for high-volume duties the place price issues most. Each change their GPT-5.6 variations.
Decrease API costs
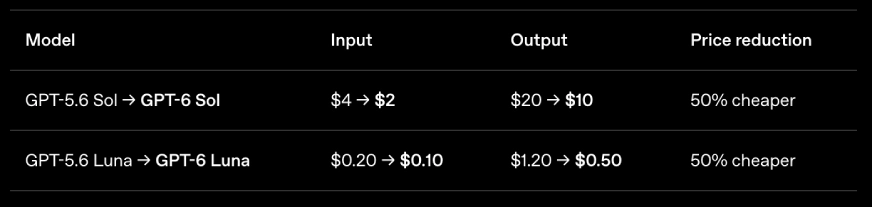
The desk beneath compares API costs for the GPT-5.6 and GPT-6 variations of every mannequin:
Supply: OpenAI
OpenAI calls this a 50% lower for each fashions. For Luna’s output, the drop is definitely bigger: $1.20 to $0.50 works out to about 58%. It credit the cuts to enhancements in caching and inference that make the fashions cheaper to serve.
Higher caching for brokers
Brokers and lengthy conversations ship the identical context again to the mannequin repeatedly. Caching lets the mannequin reuse that context as a substitute of processing it from scratch every time. OpenAI says GPT-6 will get larger cache hit charges by default, with a 90% low cost on cached enter.
Builders additionally get new instruments to trace and enhance caching. A dashboard exhibits how a lot enter will get cached, and a diagnostics device explains missed caching alternatives. Altering the reasoning effort or turning instruments on and off mid-conversation now not resets the cache. Express breakpoints let builders select the place the cached portion of a immediate ends.
GitHub studies that these enhancements lower the share of immediate tokens needing recent processing by greater than 50% throughout billions of Copilot requests.
Fewer factual errors
On OpenAI’s inner factuality take a look at, GPT-6 Sol makes about half as many errors as GPT-5.6 Sol, getting near Astra’s reliability. OpenAI says GPT-6 Luna at larger effort matches GPT-5.6 Sol at a few hundredth of the associated fee.
Clearer collaboration model
Sol and Luna inherit Astra’s communication model. OpenAI says to anticipate extra readability, much less jargon, fewer low-value particulars, and barely shorter solutions total. It says the change will present most in technical and coding conversations.
Video Supply: OpenAI
GPT-6 Sol and Luna Benchmarks
Benchmark
GPT-6 mannequin
Rating
In contrast with
Context
AutomationBench (enterprise workflows)
Sol (xhigh)
33.2%
Claude Opus 5 (max): 26.9%
Sol at 9% of Opus 5’s price per activity
Brokers’ Final Examination (skilled workflows)
Sol (max)
56.4%
Claude Opus 5’s highest rating
Sol at 60% decrease price per activity
DeepSWE v1.1 (software program engineering)
Sol (max)
68.8%
Claude Fable 5 (xhigh): 69.9%
Inside 1.1 factors, about 80% cheaper
DeepSWE v1.1 (software program engineering)
Luna (max)
66.6%
Opus 5 and Fable 5 (medium)
Comparable, 93% to 96% cheaper
OSWorld 2.0 offline (laptop use)
Sol (xhigh)
60.5%
Claude Opus 5 (medium): 60.3%
Related rating, about 80% cheaper
FrontierCode 1.1 (coding)
Sol
No quantity given
Claude Fable 5.1 (xhigh)
Described as matching Fable at a lot decrease price
The sample is constant throughout the desk: OpenAI isn’t claiming Sol or Luna beat the highest fashions outright. It’s claiming they get shut for a fraction of the associated fee.
A couple of factors assist put these numbers in context. OpenAI took competitor scores from publicly accessible studies somewhat than operating them itself, and used Claude Fable 5 scores wherever Fable 5.1 scores weren’t accessible. It additionally notes that its take a look at atmosphere might produce barely completely different outcomes from ChatGPT in on a regular basis use.
Fingers-on take a look at in ChatGPT
GPT-6 Sol and Luna can be found in ChatGPT Work and Codex for Plus, Professional, Enterprise, Enterprise, and Edu customers, however not but in common chat. Free and Go customers can strive GPT-6 Luna within the desktop app. We ran two exams on every mannequin, matched to what OpenAI says each is constructed for.
Making an attempt out GPT Sol 6
I’m going to do 2 easy duties during which I will probably be utilizing GPT Sol 6 Medium and sharing my expertise of working with the mannequin.
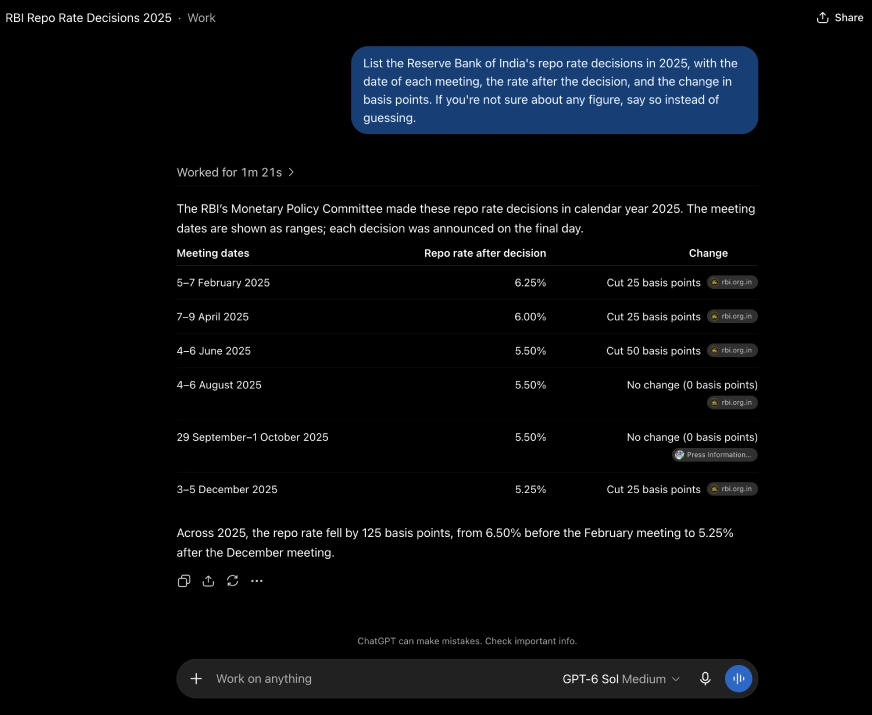
Take a look at 1: Verify the details
Immediate:
Record the Reserve Financial institution of India’s repo fee choices in 2025, with the date of every assembly, the speed after the choice, and the change in foundation factors. For those who’re undecided about any determine, say so as a substitute of guessing.
Output:
My Take:
GPT-6 Sol obtained all six 2025 repo fee choices appropriate, together with the December assembly, which I initially couldn’t verify by means of our personal search. Fairly than hedging on that determine per the immediate’s instruction, it used dwell shopping to seek out and cite the precise RBI choice, a stronger outcome than both a hedge or a guess would have been. It is a clear go, not a partial one.
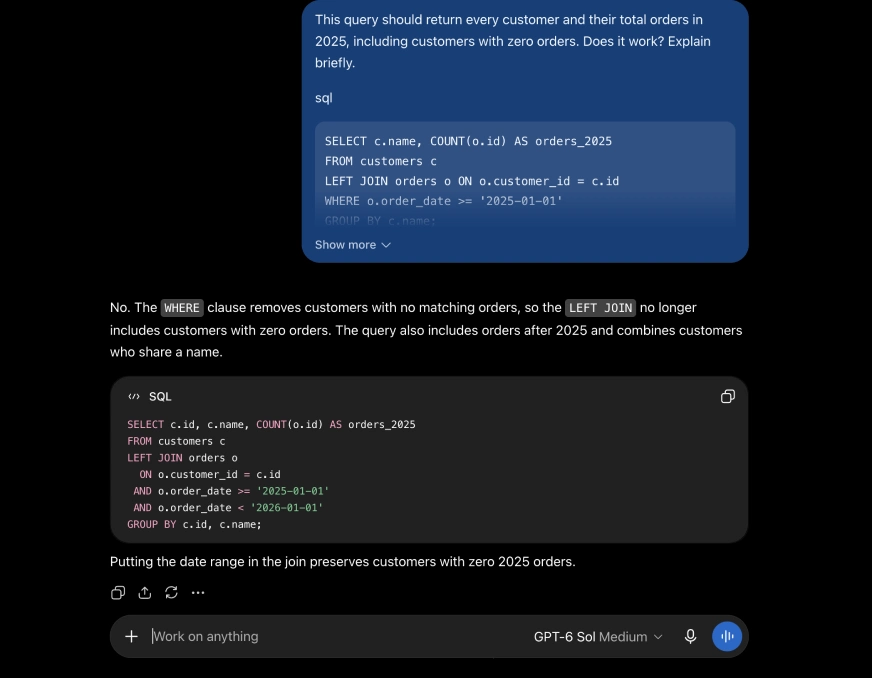
Take a look at 2: Discover the bug
Immediate:
This question ought to return each buyer and their whole orders in 2025, together with clients with zero orders. Does it work? Clarify briefly.
sql
SELECT c.identify, COUNT(o.id) AS orders_2025
FROM clients c
LEFT JOIN orders o ON o.customer_id = c.id
WHERE o.order_date >= '2025-01-01'
GROUP BY c.identify;
What to test: There are two bugs. First, filtering on o.order_date within the WHERE clause removes clients with no orders, which quietly turns the LEFT JOIN into an interior be a part of. Second, there’s no finish date, so orders from 2026 get counted too. A powerful reply catches each, strikes the date situations into the ON clause, and retains the reason brief.
Output:
My Take:
I gave GPT-6 Sol a SQL question with two planted bugs: a WHERE clause that quietly turned a LEFT JOIN into an interior be a part of, and a lacking finish date that allow orders from 2026 leak right into a 2025 report. Sol caught each, defined every clearly, and stuck the question.
It additionally caught a bug I didn’t plant. The unique question grouped outcomes by buyer identify alone, which might incorrectly merge two completely different clients who occur to share a reputation. Sol’s repair added the client ID to the grouping, a legit, non-trivial catch that went past what the take a look at requested for.
The response additionally matched OpenAI’s declare about clearer communication. It opened with a flat “No.” earlier than any rationalization, gave a set question and a one-line justification, and stayed beneath 40 phrases of prose for a bug with two meant points. No padding, no restating the query again.
Making an attempt Out GPT-6 Luna
Now, let’s see how GPT-6 Luna perfoms on real-world duties:
Take a look at 3: On a regular basis enterprise math
Immediate:
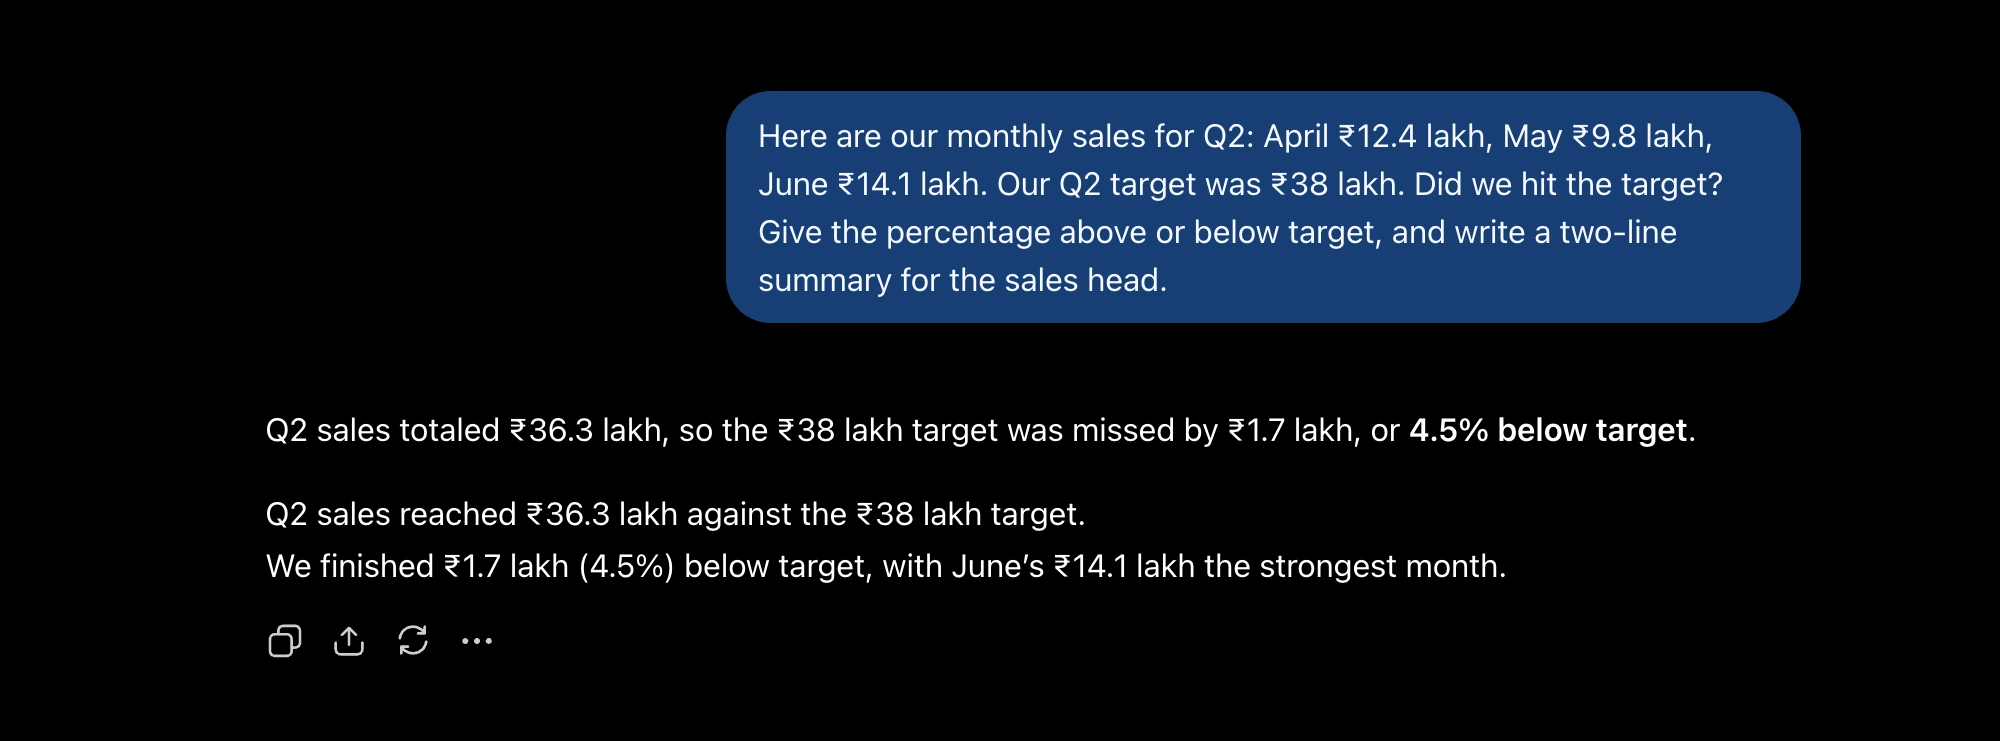
Listed here are our month-to-month gross sales for Q2: April ₹12.4 lakh, Might ₹9.8 lakh, June ₹14.1 lakh. Our Q2 goal was ₹38 lakh. Did we hit the goal? Give the share above or beneath goal, and write a two-line abstract for the gross sales head.
Output:
My Take:
It gave precisely two strains, as requested. Line one restates the numbers, line two provides a element not explicitly requested however genuinely helpful for a gross sales head: naming June because the strongest month. That’s a small little bit of initiative past the literal ask, much like what Sol did with the SQL bug hunt.
Take a look at 4: Schedule throughout time zones
Immediate:
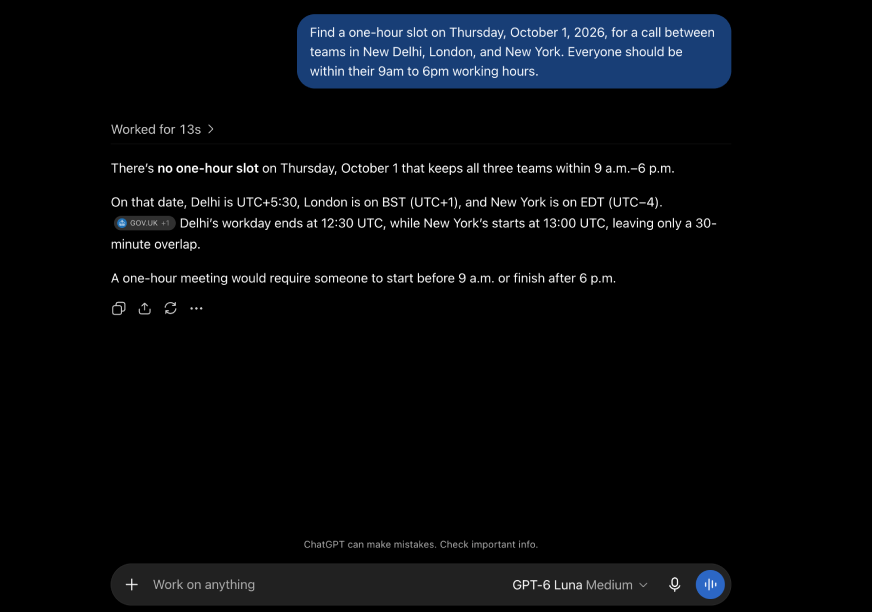
Discover a one-hour slot on Thursday, October 1, 2026, for a name between groups in New Delhi, London, and New York. Everybody needs to be inside their 9am to 6pm working hours.
Output:
I requested GPT-6 Luna to discover a one-hour name slot throughout New Delhi, London, and New York, a entice query with no legitimate reply. Luna accurately recognized that no slot exists, calculated the precise 30-minute hole, and even confirmed London was on BST (not GMT). It stopped at “no slot exists” with out suggesting a workaround. A stronger reply would have supplied a couple of compromise slots the place one group stretches barely past its working hours, making the assembly really doable as a substitute of leaving it unresolved.
Issues to Lookout for Whereas Utilizing GPT-6 Sol and Luna
A detailed studying of OpenAI’s announcement turns up 5 patterns price holding in thoughts.
Most comparisons are in opposition to Claude Opus 5, not Opus 5.5. Anthropic launched Opus 5.5 the identical day, and the 2 firms’ numbers don’t line up with one another. On AutomationBench, for instance, Anthropic studies 40.0% for Opus 5.5, above GPT-6 Sol’s 33.2%, although the 2 firms ran their exams otherwise. A number of of OpenAI’s price comparisons might already be outdated.
The trouble ranges don’t match. Sol at xhigh is in contrast with Opus 5 at max, and Luna at max with Opus 5 at medium. Every mannequin is proven at no matter setting makes the comparability look finest.
Competitor numbers are borrowed, and typically older. Competitor scores got here from public studies, and an older Claude Fable 5 rating was used wherever a Fable 5.1 rating wasn’t accessible.
The factuality positive aspects come from an inner take a look at. It’s primarily based on actual ChatGPT conversations the place customers had flagged errors, which OpenAI notes don’t symbolize typical utilization. Scores weren’t adjusted for reply size.
Most individuals can’t strive them in common chat but. The fashions are in ChatGPT Work and Codex solely, and free customers get Luna within the desktop app alone. For a lot of readers, the API or the desktop app is the one approach to take a look at these claims in the present day.
Conclusion
GPT-6 Sol and Luna don’t declare to be the neatest fashions accessible. OpenAI retains that title for Astra. The pitch is closer-to-frontier efficiency at half the value, backed by caching enhancements that might matter as a lot as the value lower for anybody operating brokers. The 50% worth lower is concrete. The benchmark comparisons want extra care: most are in opposition to Claude Opus 5, which was changed the identical day by a less expensive, stronger Opus 5.5. With each firms now competing on price, the actual take a look at is operating Sol, Luna, and their rivals on the identical duties you do every single day.
For extra such informational content material, comply with Analytics Vidhya weblog.
Howdy, I’m Nitika, a tech-savvy Content material Creator and Marketer. Creativity and studying new issues come naturally to me. I’ve experience in creating result-driven content material methods. I’m nicely versed in search engine optimisation Administration, Key phrase Operations, Internet Content material Writing, Communication, Content material Technique, Modifying, and Writing.
Login to proceed studying and luxuriate in expert-curated content material.
This isn’t one other of these ‘AI is killing jobs’ stories. Anthropic, in a brand new analysis, appears to have requested the deeper questions this […]
OpenAI has launched GPT-6 Astra, its latest frontier mannequin, lower than every week after Anthropic’s Claude Fable 5.1. OpenAI calls Astra the world’s most clever […]