Pegasus supplies temporal context, spatial reasoning, and judgement on whether or not a activity was accomplished. Supply: TwelveLabs
Because the bodily world quickly digitalizes, AI groups are gathering huge quantities of advanced video, however reworking uncooked footage into actionable fashions stays a vital problem, based on TwelveLabs Inc. The corporate in the present day launched its Pegasus 1.6 mannequin with added capabilities for understanding and navigating advanced real-world environments.
“Our mission has all the time been to assist machines perceive how the world works via video,” acknowledged Jae Lee, co-founder and CEO of TwelveLabs. “Bodily AI is the following expression of that mission. Most of what individuals learn about doing bodily work, reminiscent of a altering grip or a restoration after one thing slips, has by no means been captured in a type a machine can study from.”
“With our latest mannequin launch, we will now flip that footage into structured, reviewable data, so robotics and bodily AI groups can practice on actual human expertise as an alternative of ranging from scratch,” he added.
Based in 2021, TwelveLabs stated it has created a “full-stack video intelligence platform” utilizing its Marengo and Pegasus fashions, which it designed to see and perceive video the way in which people do in a fraction of the time. Builders can use this single system that will get smarter over time to entry and act on all of their video content material, stated the Seoul-based company.
Pegasus 1.6 focuses on selfish video
TwelveLabs stated its newest model of Pegasus marks its growth into physical AI, producing wealthy insights from real-world views. It solves workflow-specific challenges in order that machines reminiscent of robots, drones, and autonomous autos can understand, motive, and safely act within the bodily world like by no means earlier than, the corporate claimed.
“We’re centered on the video understanding layer,” Jae Lee informed The Robotic Report. “You’ll be able to’t simply take hundreds of thousands of hours of video and feed it right into a robotics mannequin and count on helpful coaching knowledge to come back out. You first want to grasp what’s occurring within the video, what motion is happening, when it occurs, what the particular person is interacting with, how the habits adjustments over time, and when different individuals or bystanders seem within the discipline of view.”
“Pegasus 1.6 supplies that extra exact understanding so robotics and knowledge groups can then flip it into the coaching knowledge they want,” he added.
TwelveLabs famous that Pegasus 1.6 is its first AI mannequin constructed to grasp selfish video, which is shot from the viewpoint of the particular person doing the work. This may very well be somebody cooking a meal, assembling components on a manufacturing unit line, or working a robotic remotely. The mannequin doesn’t require particular cameras, stated Lee.
“We’re not requiring robotics groups to make use of a selected digital camera or proprietary {hardware} to seize that footage,” he stated. “What issues is with the ability to seize the actions and interactions happening from the operator’s viewpoint.”
As well as, Pegasus 1.6 can work with current video knowledge and permits for evaluation of nonetheless photos along with video.
“One of many causes we’re centered on selfish video is that it’s a lot simpler to gather and scale than teleoperation knowledge,” acknowledged Lee. “The aim is to take that footage and make it extra helpful for robotics groups by figuring out the actions happening, breaking them into exact time segments and capturing finer-grained particulars in regards to the habits.”
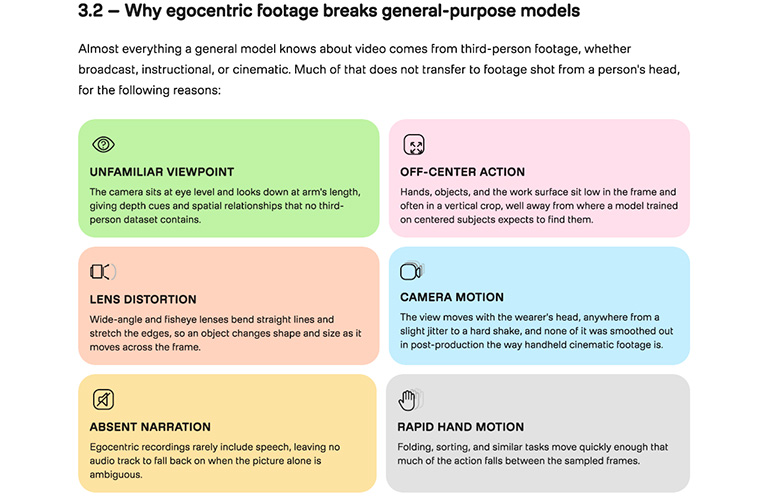
Head-mounted footage can break fashions skilled on broadcast, tutorial, and cinematic video. Supply: TwelveLabs
TwelveLabs helps 5 workflows
Pegasus 1.6 at the moment helps 5 workflows powered by its video-native mannequin. They embody:
- Motion segmentation and labeling: This function accelerates mannequin coaching with standardized datasets by mechanically producing exact, time-stamped motion labels for duties, steps, objects, and hand-object interactions from uncooked video, mapped to the shopper’s domain-specific taxonomy.
- Dense caption labeling: This permits pure language understanding for robots by producing wealthy, descriptive language for spatial relationships, scene context, and hand-object interactions to coach superior language-conditioned robotic insurance policies.
- High quality scoring: Customers can save time by filtering out low-quality video by mechanically evaluating and scoring video clips for motion readability, framing, and stability earlier than sending footage to human reviewers.
- Search and curation: Clients can uncover vital edge instances by surfacing uncommon occasions, long-tail situations, and duplicate clips throughout a whole video repository utilizing easy, natural-language search queries.
- Consent and compliance flagging: Privateness and compliance may be maintained by detecting and flagging faces, bystanders, and delicate onscreen or paper knowledge earlier than video footage enters downstream growth pipelines.
Editor’s be aware: Bodily AI is among the many session monitor matters at RoboBusiness 2026, which might be on Oct. 20 and 21 in Santa Clara, Calif. Register now to attend.
 Register now and assist us have fun 20 years of RoboBusiness!
Clients to profit from current capabilities
Pegasus 1.6 builds on the video understanding capabilities that TwelveLabs developed for enterprises that keep huge video libraries.
The brand new launch extends Pegasus 1.5’s performance that attracted a number of new prospects. TwelveLabs cited Time-Based mostly Metadata (TBM), which permits customers to outline a customized schema and mechanically obtain timestamped, structured metadata from video content material. That is notably helpful in aiding contextual understanding, as individuals typically narrate what they’re doing in selfish clips, it stated.
Pegasus 1.6 has additionally improved entity recognition for extra constant monitoring of palms, objects, and instruments throughout clips. The mannequin additionally provides sooner, extra cost-efficient processing for high-volume video workloads, based on TwelveLabs.
Lee stated that TwelveLabs’ system provides video understanding to different sensor modalities.
“We’re centered on understanding the habits we will observe within the video,” he stated. “Pegasus 1.6 can establish the motion happening, section it exactly in time, perceive what the left and proper palms are doing, and the way the encompassing surroundings is altering.”
“We will additionally present a rough understanding of how the limbs are transferring based mostly on the video, however we’re not attempting to interchange the robotic’s tactile or actuator-level sensing,” he added. “Our position is to present robotics groups a richer understanding of the habits within the video that they will mix with their very own sensor knowledge to construct extra exact trajectories and studying insurance policies.”
TwelveLabs stated that Pegasus 1.6 expands on its current collaborations with robotics builders.
“We’re working with robotics labs and knowledge groups which might be utilizing video to assist scale the info obtainable for robotic coaching,” stated Lee. “Plenty of the work is targeted on dexterity and manipulation, duties like packaging, meeting, and cleansing, in addition to extra specialised industrial functions reminiscent of semiconductor high quality management. The broader aim is to assist these groups make a lot bigger quantities of human behavioral video helpful for coaching, which is much extra scalable than teleoperation knowledge.”
The put up Pegasus 1.6 brings video understanding to bodily AI, says TwelveLabs appeared first on The Robotic Report.