In case you observe developments within the AI world, chances are high you’ve got already come throughout Jev, a brand new AI mannequin by TypeSafe AI. It’s trending on X, and when you perceive the rationale behind it, you’ll want to strive it out for your self.
TypeSafe AI got here out of two years in stealth on September 15, 2026, backed by $40 million in seed funding. Founder Diogo Almeida spent years at OpenAI, the place he helped construct the analysis behind ChatGPT. Within the firm’s personal phrases, fashions have been superhuman at chat for years, so why has all of the automation not caught up? That query is what led Almeida to construct TypeSafe: AI infrastructure meant not for dialog, however for choices inside software program.
On this article, we are going to clarify what Jev is, why it issues, and the way it’s completely different from ChatGPT, Claude, and different LLMs you already use.
What’s Jev?
Jev will not be a chatbot. It can not write emails, poems, or code. The truth is, it can not generate textual content in any respect. In line with TypeSafe, that’s the level.
Fashions like ChatGPT, Claude, and Gemini generate responses one token at a time. This makes them versatile and conversational, but additionally slower and inherently open-ended. Jev takes a special strategy. It analyzes a state of affairs as soon as and returns a hard and fast, predefined reply with a confidence rating. As an alternative of producing a response, it makes a judgment.
As a result of Jev doesn’t generate textual content sequentially, it may well course of its output in parallel. This makes it quicker, extra predictable, and doubtlessly cheaper to run.
The video is taken from the official documentation. You’ll be able to fidn extra particulars here.
The way it works?
A daily LLM writes one token at a time, and every new token depends upon the one earlier than it. This chain is what makes these fashions slower when used inside software program, and it’s unavoidable so long as the output is a sentence.
Jev skips this completely. It reads the state of affairs as soon as, then solutions each query you requested in a single move, all on the identical time.
Let’s take an instance of a buyer assist ticket that must be routed and prioritized. A conventional system would possibly depend on key phrase guidelines or handbook overview. With Jev, a developer can consider a number of features of the ticket without delay, resembling which workforce ought to deal with it and whether or not it’s pressing:
from typesafe_sdk import Selection, Noul, TypeSafeClient

response = TypeSafeClient().system_one(
    state=ticket,
    questions={
        "division": Selection(
            directions="Which workforce ought to deal with this ticket?",
            standards={
                "billing": "Cost points",
                "technical": "Bugs or integrations",
            },
        ),
        "is_urgent": Noul(
            directions="Is that this ticket time-sensitive?"
        ),
    },
)

response.solutions["department"].selection   # "technical"
response.solutions["is_urgent"].noul      # 1.0
Jev analyzes the ticket as soon as and returns each outcomes collectively. There isn’t a have to course of every query individually or look ahead to one response earlier than evaluating the subsequent.
This one name additionally reveals the three forms of questions Jev can deal with:
- Selection: Selects one possibility from a predefined set, resembling the suitable assist division
- Rating: Assigns a worth to one thing primarily based on an outlined scale
- Noul: Returns a likelihood between 0 and 1 for a sure/no query, resembling whether or not a ticket is pressing
These query sorts might be mixed freely in a single request, with outcomes returned concurrently slightly than generated one after one other.
One consequence of that is price pausing on. Including extra inquiries to a single name barely modifications how lengthy it takes to get a solution. Asking Jev one query or 13 questions takes roughly the identical period of time. TypeSafe’s personal cookbook reviews that batching 13 questions into one request got here out 12.2 instances cheaper and 10 instances quicker than asking them one after the other, with no change within the solutions.
Jev in Motion: Examples
Jev has launched with restricted entry, and since we do not need hands-on entry but, we’re exhibiting examples from X to see the way it performs throughout completely different duties.
Instance 1: Scoring Leads and Outreach at Scale
One builder, Roman, examined Jev on 700 high-intent leads paired with customized outreach messages. In 40 seconds and for about $0.09 whole, Jev predicted how every message would carry out, hooked up a confidence rating, and flagged mismatches between leads and messages. The identical builder famous Jev may also rating leads, learn shopping for indicators, match prospects to the best-fit message, and determine which campaigns are prone to carry out primarily based on the info.
Instance 2: Studying 464,720 Analysis Papers
One researcher, DevaiahShrithan, ran each arXiv AI summary from 1993 to 2026 by way of Jev, asking 5 questions of every: does it declare cutting-edge, did it launch code, is it written in LLM model, what sort of paper is it, and the way hyped is the language. The output is a chart of how AI analysis writing has modified over three many years, constructed from 2.3 million particular person judgments.
Instance 3: Triaging 3 Million Session Replay Occasions
One other builder, Tarasshyn, pointed Jev at 3 million session-replay occasions. In 40 seconds and for $2.17, it reviewed 3,247 periods, caught 132 rage clicks, 116 lifeless clicks and 95 JavaScript errors, then opened 213 draft repair pull requests. The attention-grabbing half is the final step: the judgments had been adequate to behave on routinely, not simply to show on a dashboard.
Jev Evals
TypeSafe backed the launch with some putting numbers. Enter prices $0.042 per million tokens, and output is free since there may be nothing generated to invoice for. At that value, a bot taking part in Doom and making ten choices a second runs about $7 an hour.
TypeSafe was upfront that all of those figures comes from its personal evals, utilizing its personal workflows and reference solutions, with no impartial verification but. That transparency didn’t cease critics from calling Jev little greater than a well-packaged classifier, a class of device that has existed for years.
What that critique misses is that classification was by no means the true declare. Calibration was. A calibrated mannequin’s confidence scores imply one thing particular: the solutions it scores at 0.8 are proper about 80% of the time. That’s what lets code act routinely on high-confidence solutions and escalate the remainder, which is the distinction between a demo and one thing production-ready.
Probably the most convincing end result, although, was not one of many flashy demos. TypeSafe’s re-ranking cookbook takes 40 authorized queries, builds a 30-passage shortlist for every utilizing strange key phrase search, then asks Jev a single query per query-passage pair. That one additional step greater than tripled top-1 accuracy.
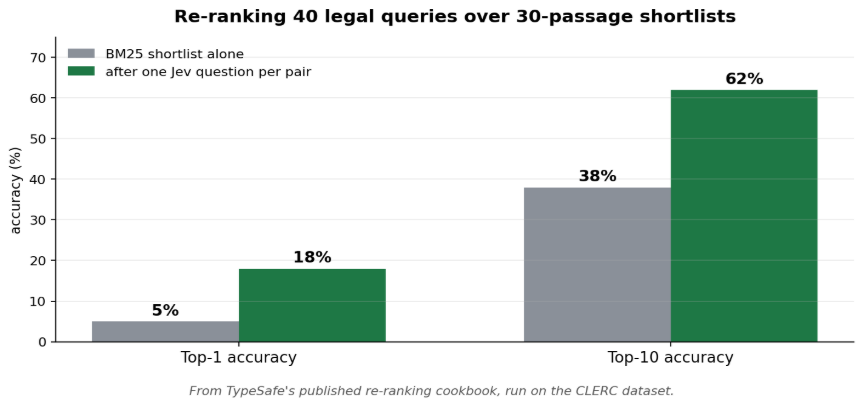
Like every thing else right here, the quantity is TypeSafe’s personal. However the underlying sample nonetheless holds: at this value and pace, calling a mannequin ten instances a second stops being reckless.
Hallucinations, RLCD, and The place Jev Breaks
TypeSafe’s “no hallucinations” declare wants a caveat. Jev can not return a worth outdoors the set you outlined, so it may well by no means hand your code one thing unparseable. However it may well nonetheless provide the flawed reply from inside that set. Kind security and correctness are completely different ensures, and solely the primary is absolute.
That honesty extends to how Jev was educated. Most fashions use RLHF, which quietly rewards confident-sounding solutions, or RLVR, educated on outputs a program can confirm. TypeSafe constructed a 3rd methodology, RLCD, aimed particularly at sincere possibilities. Notably, Jev’s founder co-invented RLHF at OpenAI, then constructed a technique designed round its personal blind spot.
TypeSafe can be unusually upfront about the place Jev fails, itemizing 9 failure modes in its docs. A couple of price understanding: it struggles with arithmetic and dates (preserve these in code), and with massive, noisy enter (filter first).
Conclusion
On paper, Jev’s pitch is compelling: quicker, cheaper, and designed for decision-making slightly than dialog. Nevertheless, the figures mentioned on this article, together with pricing, accuracy, and pace, are primarily based on TypeSafe’s personal evaluations and workflows. They haven’t but been independently verified, and real-world efficiency can differ from managed benchmarks.
The extra essential query is how nicely Jev suits into real-world improvement workflows. OpenAI and Anthropic have spent years constructing mature APIs, integrations, and developer tooling. Jev is a more recent strategy that also must show how simply it may well match into current techniques and manufacturing environments.
For now, the benchmarks are greatest seen as a sign of Jev’s potential slightly than a definitive measure of manufacturing efficiency. We’ll have a clearer image as soon as we’ve examined it ourselves.
Keep tuned for our hands-on article, the place we put Jev’s claims to the take a look at.
Steadily Requested Questions
A. No. It can not write, converse, or cause open-endedly. Most early builds run it alongside an LLM, letting Jev deal with routing and verification whereas the chat mannequin does something that wants producing.
A. It can not return a worth outdoors your schema or a malformed response. It might probably nonetheless return the flawed worth from inside it. Two completely different ensures, and solely the primary is absolute.
A. $0.042 per million enter tokens, output free.
A. No. The identical weights serve everybody, and TypeSafe says it isn’t educated on buyer requests. You adapt it by way of the request as an alternative: your materials within the state, your guidelines within the directions and standards.

Hello , I’m Sree Vamsi a passionate Information Science fanatic at present working at Analytics Vidhya. My journey into knowledge science started with a curiosity for uncovering insights from advanced knowledge and has developed into constructing end-to-end Generative AI purposes, RAG pipelines, agentic AI workflows, and multi-agent techniques that remedy real-world enterprise issues.
Login to proceed studying and luxuriate in expert-curated content material.